deepseek-v4-pro-qwen3.5-9b-uncensored-heretic explained: teacher data, Qwen weights, ARA edits
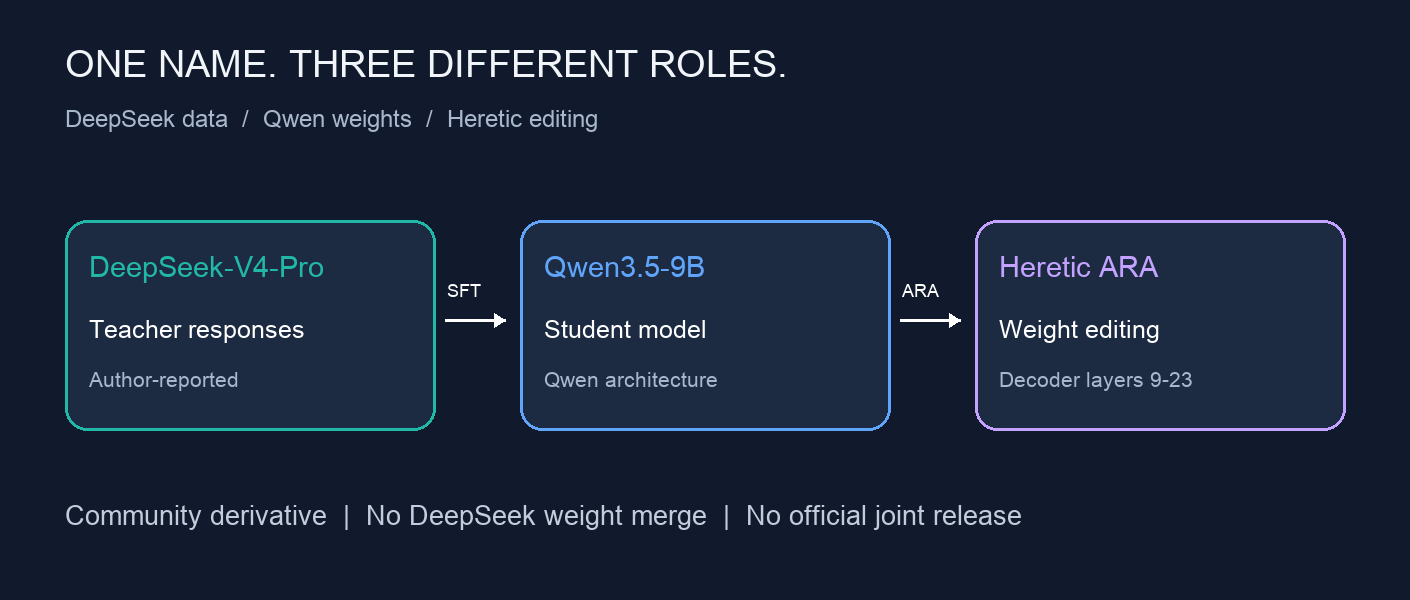
deepseek-v4-pro-qwen3.5-9b-uncensored-heretic is a community derivative built on Qwen3.5-9B. DeepSeek supplies the claimed teacher responses and the name; Heretic edits the resulting Qwen student. This is a response-distillation lineage, with no DeepSeek weight merge or official involvement in the community release.
Throughout this article, 【Verified】 means supported by public files or source code; 【Author claim】 means reported by a model maintainer without independent reproduction. Sources were checked on November 10, 2026.
What the deepseek-v4-pro-qwen3.5-9b-uncensored-heretic name actually describes
【Author claim】Jackrong says approximately 250,000 mathematics and STEM examples were generated using DeepSeek-V4-Pro, followed by supervised fine-tuning and a light GSPO reinforcement-learning stage. The author says neither stage included coding data. This describes learning from generated responses, rather than copying teacher parameters. Public evidence does not establish a token-level logit-distillation procedure. Upstream HF model card
The teacher identity, sample count and training sequence remain attributed claims: the release does not provide the dataset, generation logs and complete training records needed to independently verify them. “Max Effect” is the author's wording, not a verified official mode name here.
DeepSeek was not an official participant in this community release. The public lineage runs through Qwen, unsloth, Jackrong and xtools-at; thanking a teacher-model provider does not establish a partnership. No public evidence of official involvement was found. Student card, heretic card
The checkpoint remains a Qwen model
【Verified】The official Qwen, student and heretic configurations identify Qwen3_5ForConditionalGeneration. Their language configuration differs substantially from DeepSeek's:
| Field | Qwen / student / heretic | DeepSeek-V4-Pro |
|---|---|---|
| Architecture | Qwen3_5ForConditionalGeneration | DeepseekV4ForCausalLM |
| Hidden size | 4096 | 7168 |
| Language layers | 32 | 61 |
| Vocabulary size | 248,320 | 129,280 |
Sources: Qwen config, student config, heretic config, DeepSeek config.
Both current student and heretic indexes contain 775 tensor keys, retaining Qwen language, vision and MTP naming. Together with the declared lineage, this supports a post-trained Qwen derivative. There is no evidence of merged DeepSeek weights, and the configurations do not permit an ordinary tensor-by-tensor weighted merge. An index establishes structure, however, not the complete training history of every value. Student index, heretic index
ARA targets decoder layers 9–23
【Verified】The heretic card records Heretic v2.0.0.dev0 and Arbitrary-Rank Ablation. Its start index is 9 and exclusive end index is 24: 15 language decoder layers numbered 9 through 23, using zero-based numbering. HF parameter table
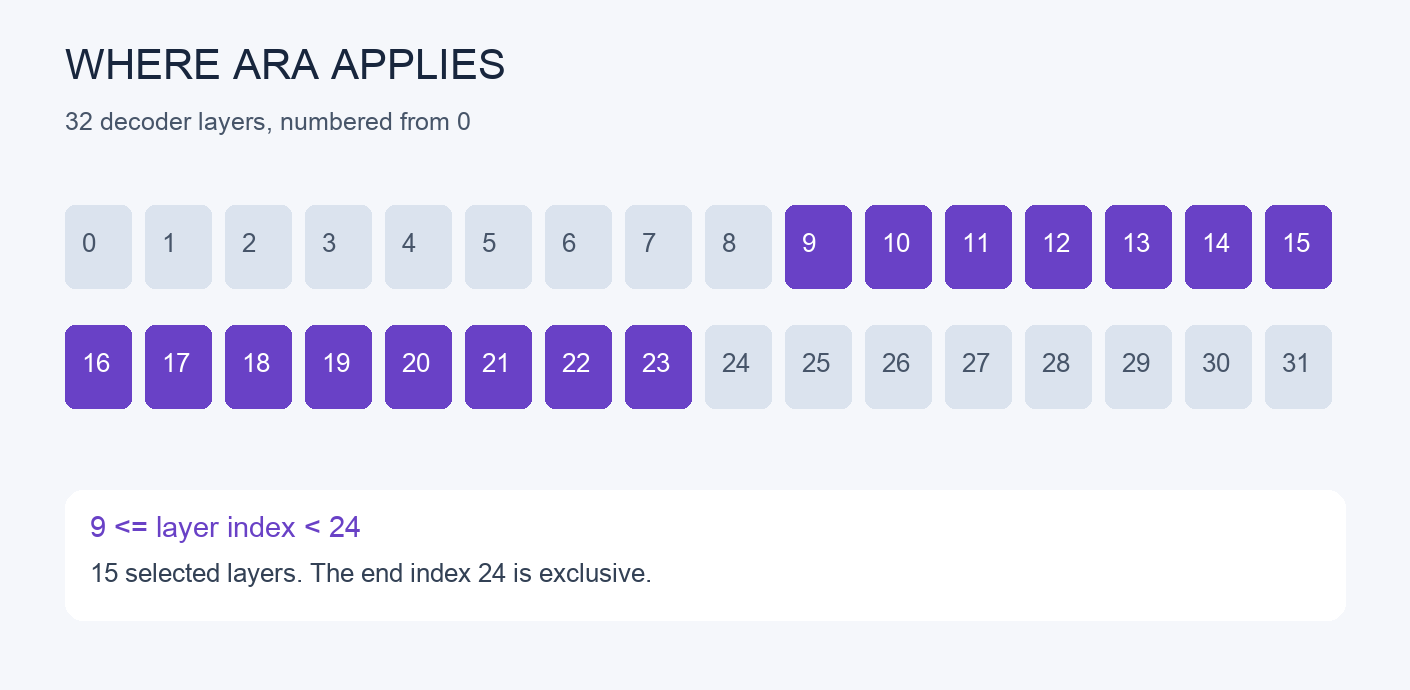
ARA should not be described as subtracting one refusal direction. Its author describes direct matrix optimization of selected modules, balancing preservation of one prompt group's outputs with changes to another group's outputs. The method edits the distilled Qwen checkpoint; it introduces no DeepSeek architecture or tokenizer. ARA technical explanation
Read the performance numbers with their scope attached
【Author claim】The heretic maintainer reports refusals falling from 100/100 to 3/100 and KL divergence of 0.0422. These are results under that evaluation setup, not a universal 3% refusal probability or an independent safety audit. Low KL does not establish preservation of every capability. Heretic performance table
The reported GSM8K 94.50% and MMLU-Pro 90.53% belong to the upstream distilled model's author evaluation. GSM8K is labeled a four-run NVFP4/vLLM average. MMLU-Pro covers 500 questions each from mathematics, physics and chemistry, rather than the full benchmark. Neither is an independently reproduced heretic score or proof of broad superiority over a 70B model or its teacher. Upstream methodology
Math and STEM are the reported training emphasis and sensible subjects for further evaluation. Coding, tool use, image understanding and creative quality still need version-specific evidence. Retaining a vision tower does not verify vision quality; answering more requests does not verify accuracy.
The MTP incident illustrates a separate compatibility question
【Verified】HF discussion #1 records an earlier index with 760 keys and no mtp.* tensors, versus 775 keys including 15 MTP tensors upstream. The maintainer said the missing tensors were restored. The current index checked for this article contains those 15 keys. Discussion, current index
That verifies current file structure, not every downstream quantization or runtime combination. Likewise, a roughly 5.6GB quantized file is a weight-file size, not a complete memory budget: caches, vision components and runtime overhead remain separate. This article makes no unmeasured hardware promise and excludes changing download counts, rankings and unsupported outage stories.
For this model family, check four things separately: the source of the model body, the evidence for teacher data, the exact checkpoint evaluated, and the effects of the later edit. The supported description is a Qwen3.5-9B student reportedly trained on DeepSeek responses, followed by community ARA edits to layers 9–23. Independent task-specific evaluation is still needed.
Latest from the blog
New research, comparisons, and workflow tips from the Vibe Coding Tools team.
Follow a real DeepSeek Superagent task through five screenshots: submit a request, inspect routing, watch a Worker create a file, and learn when its session is reused.
Understand Xiaomi-OCR-0 with a simple training analogy: 170M samples, Q-Mask, CPT and Mix-RL. Compare official scores and try document parsing locally with Ollama or Transformers.
Learn how DeepSeek Super Agent routes work to Workers and subagents, who the research prototype suits, and how to start with one small task in a test repository.